CLIP-6D
Empowering CLIP as a Zero-Shot 6D Pose Estimator Through Generalizable Object-Specific Representations
ACM Multimedia 2025 · Oral
From an RGB image, depth, and an object category name, CLIP-6D estimates the 3D position and 3D orientation of objects from categories unseen during training.
Motivation
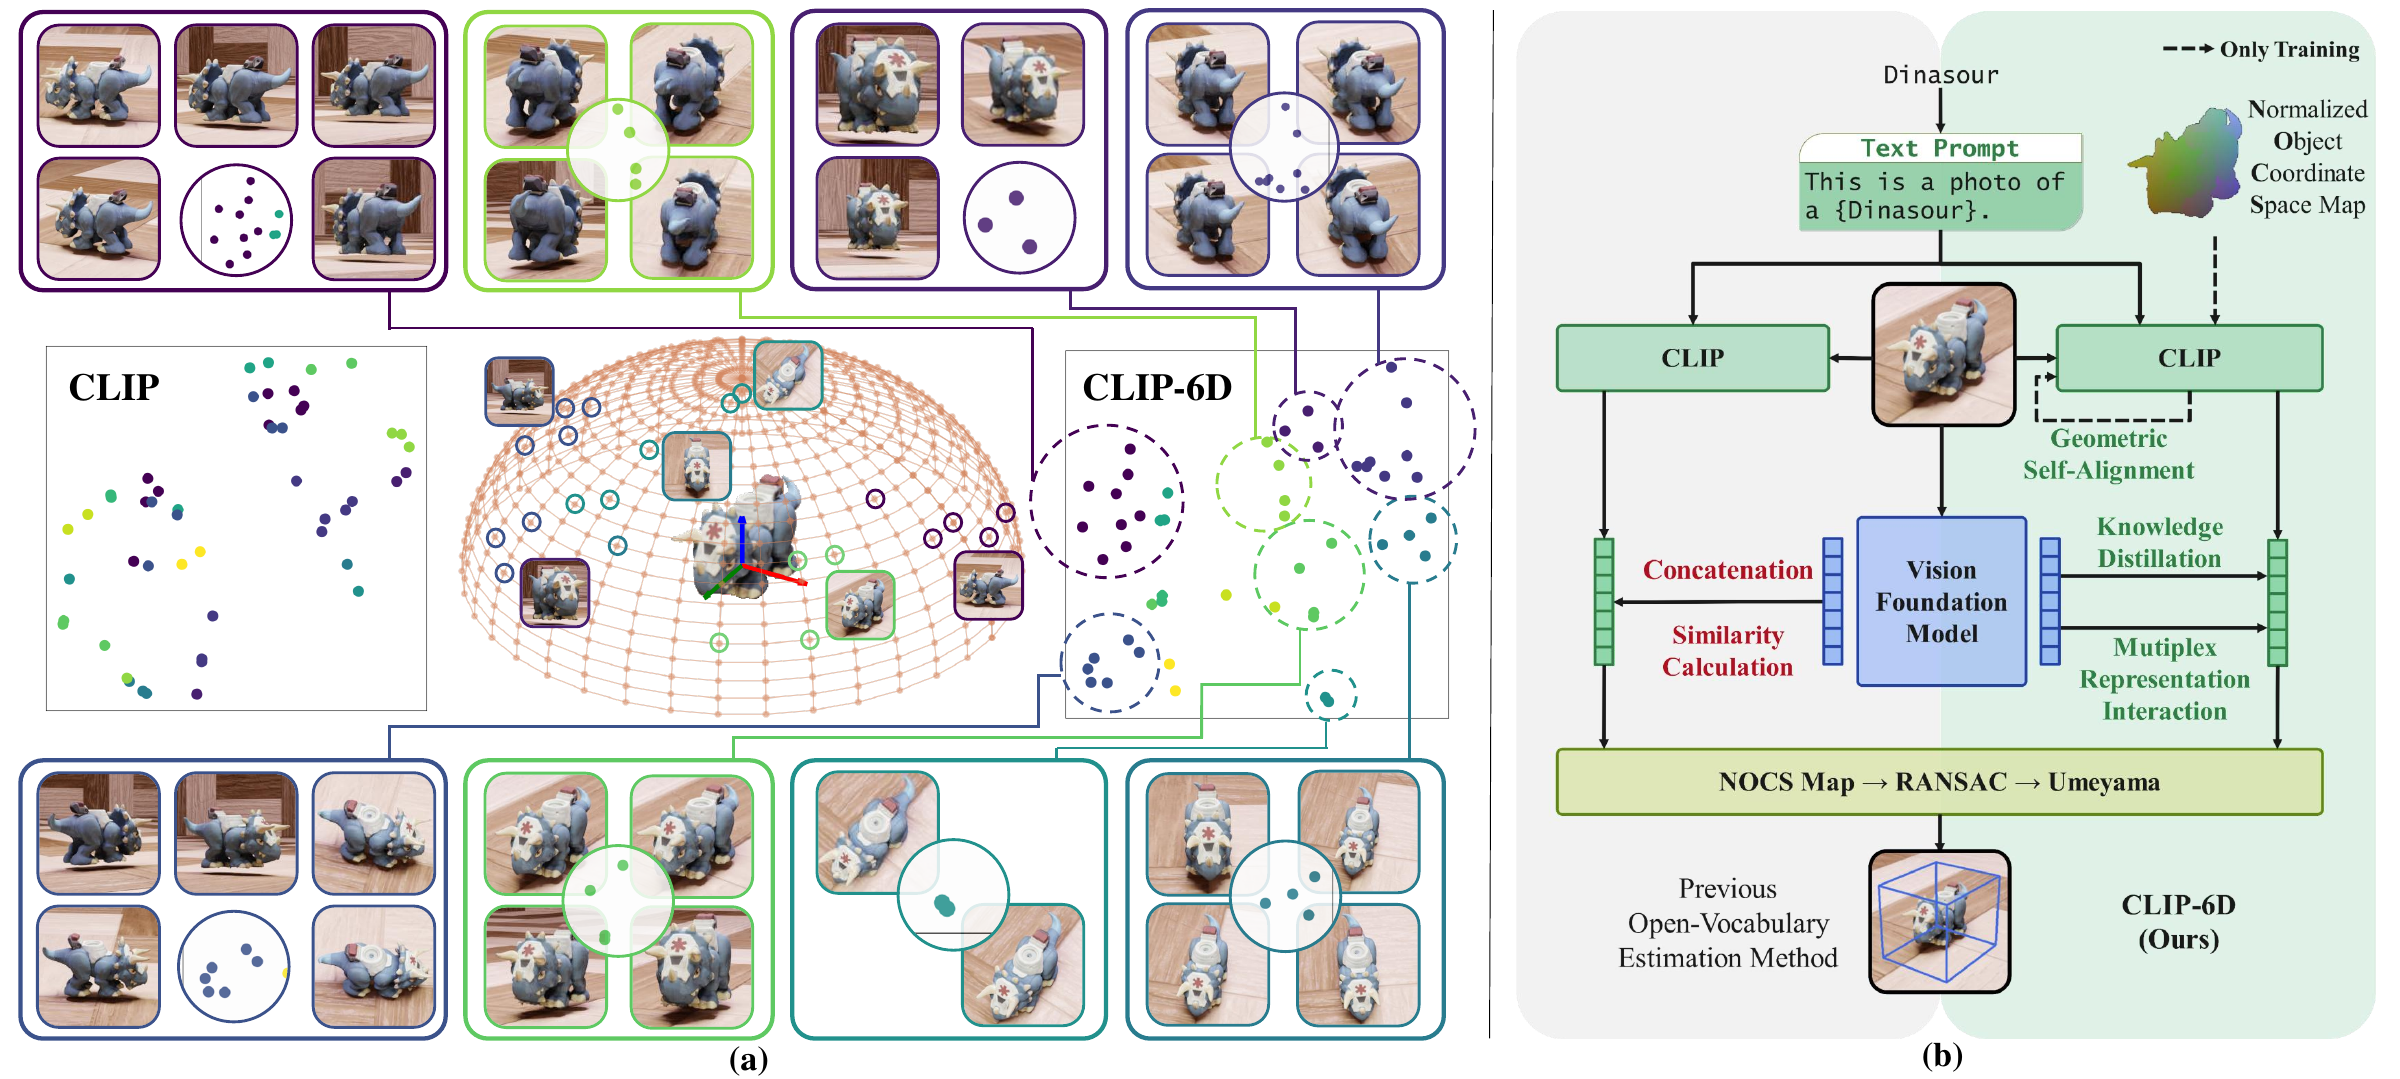
Open-vocabulary pose estimation builds on vision-language models (VLMs) to connect category names with images, and vision foundation models (VFMs) to provide transferable visual features. However, pretraining objectives such as image–text alignment and self-supervised visual learning do not directly optimize for 6D pose. This leaves a gap between the learned feature space and the object’s 3D position and 3D orientation.
CLIP-6D improves how CLIP acquires generalizable object representations in four aspects: object geometry, sensitivity to the relative positions of object parts, fine-grained semantics, and effective feature fusion. Geometric self-alignment adds geometric cues; representation interaction combines semantic, spatial, and geometric features; and fine-grained semantic distillation captures local details.
How it works
At inference, the model uses an RGB image, depth, the category name, and camera intrinsics. It needs no CAD model or reference poses for the test object.
Learn geometric cues
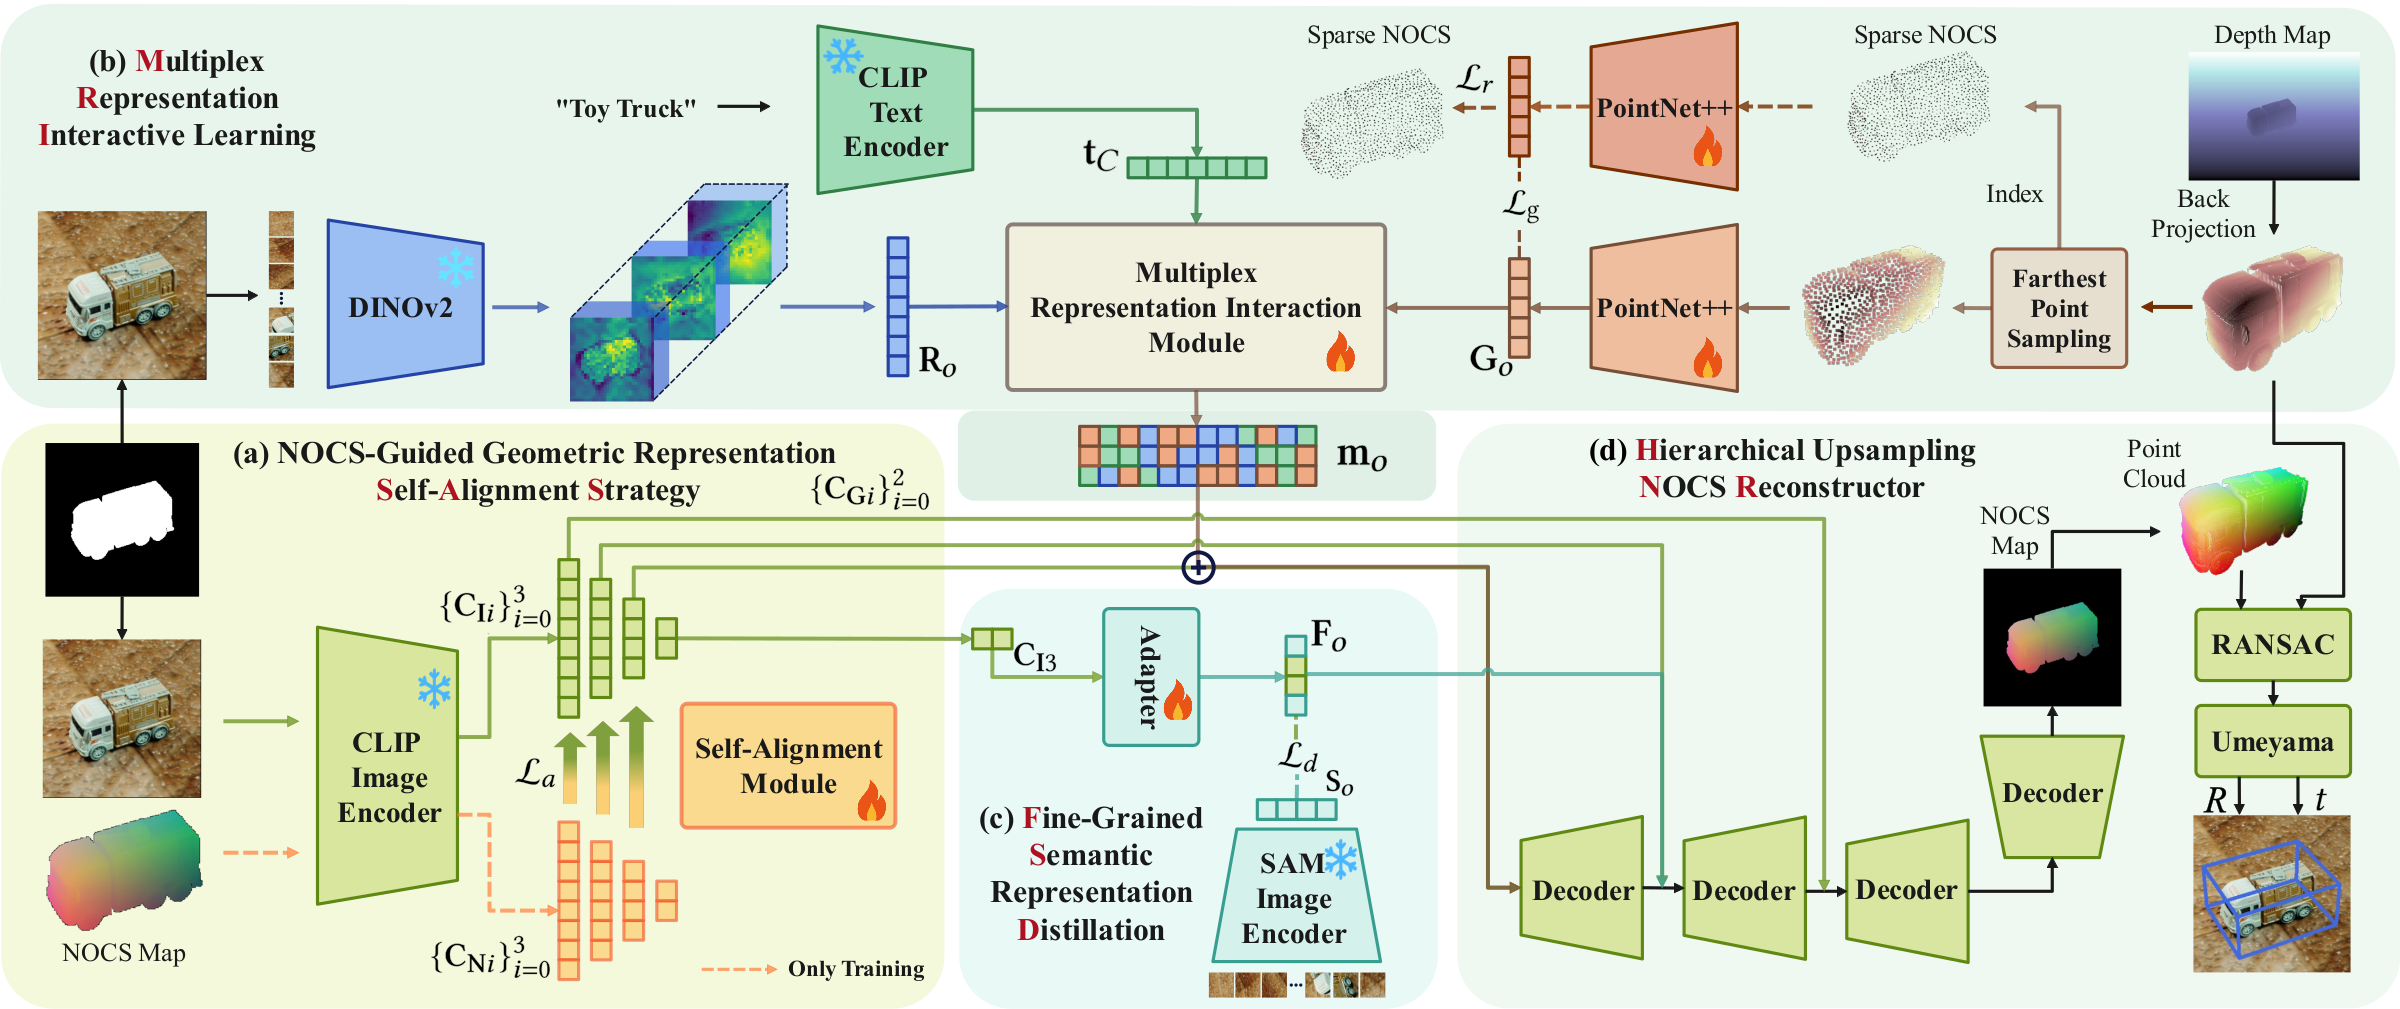
An alignment module learns geometric cues from CLIP’s fixed RGB features, using normalized 3D coordinates as training supervision. These coordinates are not required as an input at test time.
Bring the cues together
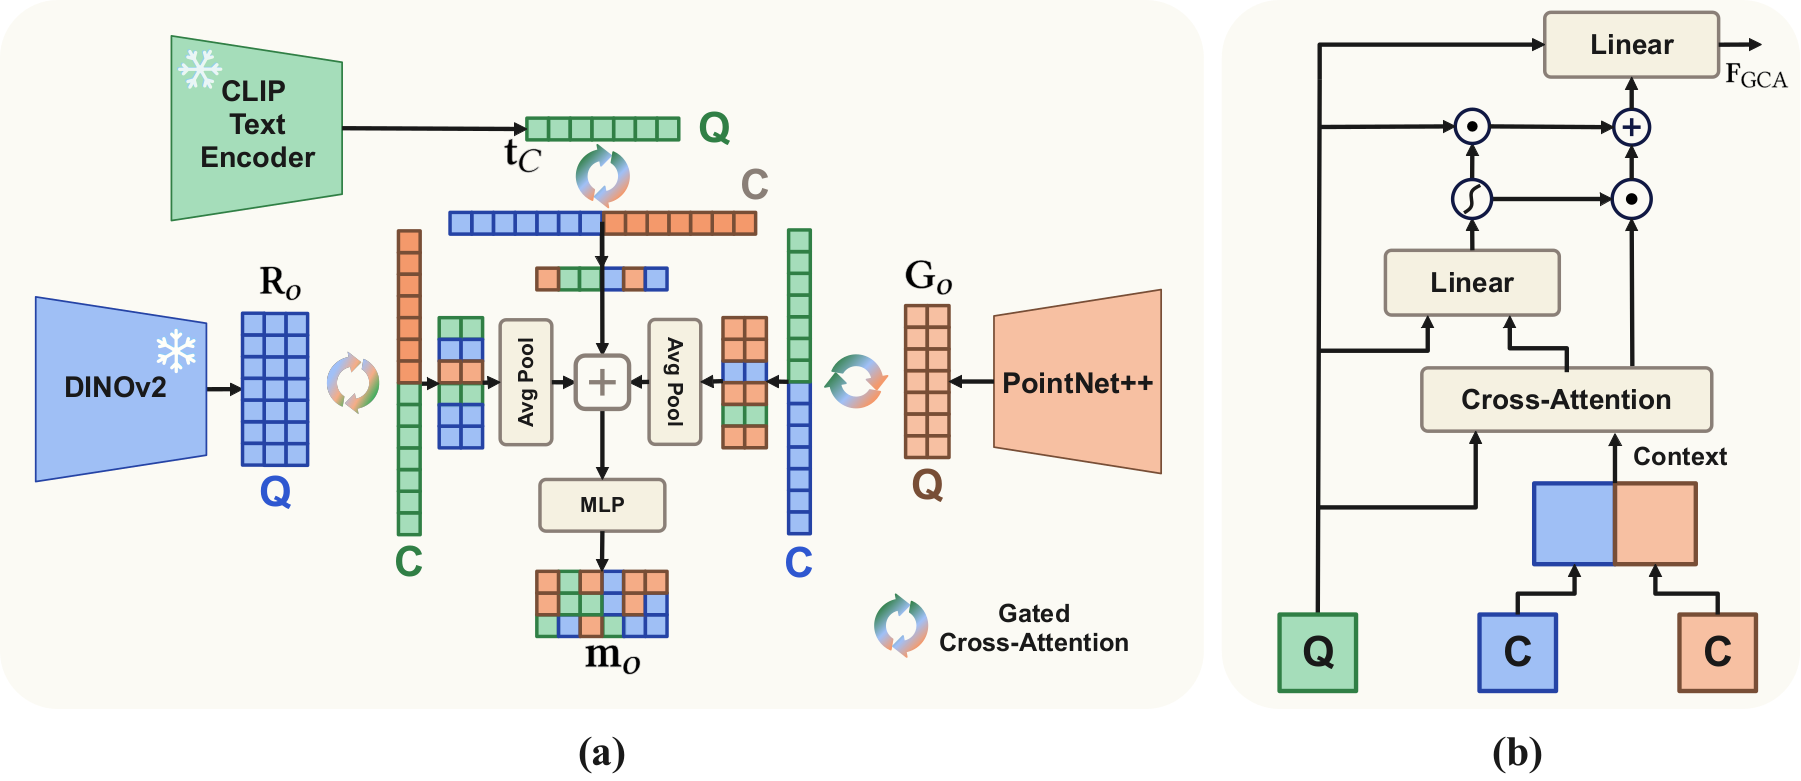
Gated attention combines category information from CLIP, spatial relationships from DINOv2, and geometry from the depth point cloud.
Preserve fine details
A lightweight adapter learns fine image details from SAM during training, avoiding the need to run the full SAM encoder at inference.
More detail: the representation interaction module
Each cue attends to the other two. Learned gates balance the incoming information with the original features, producing one object-specific representation.
Results
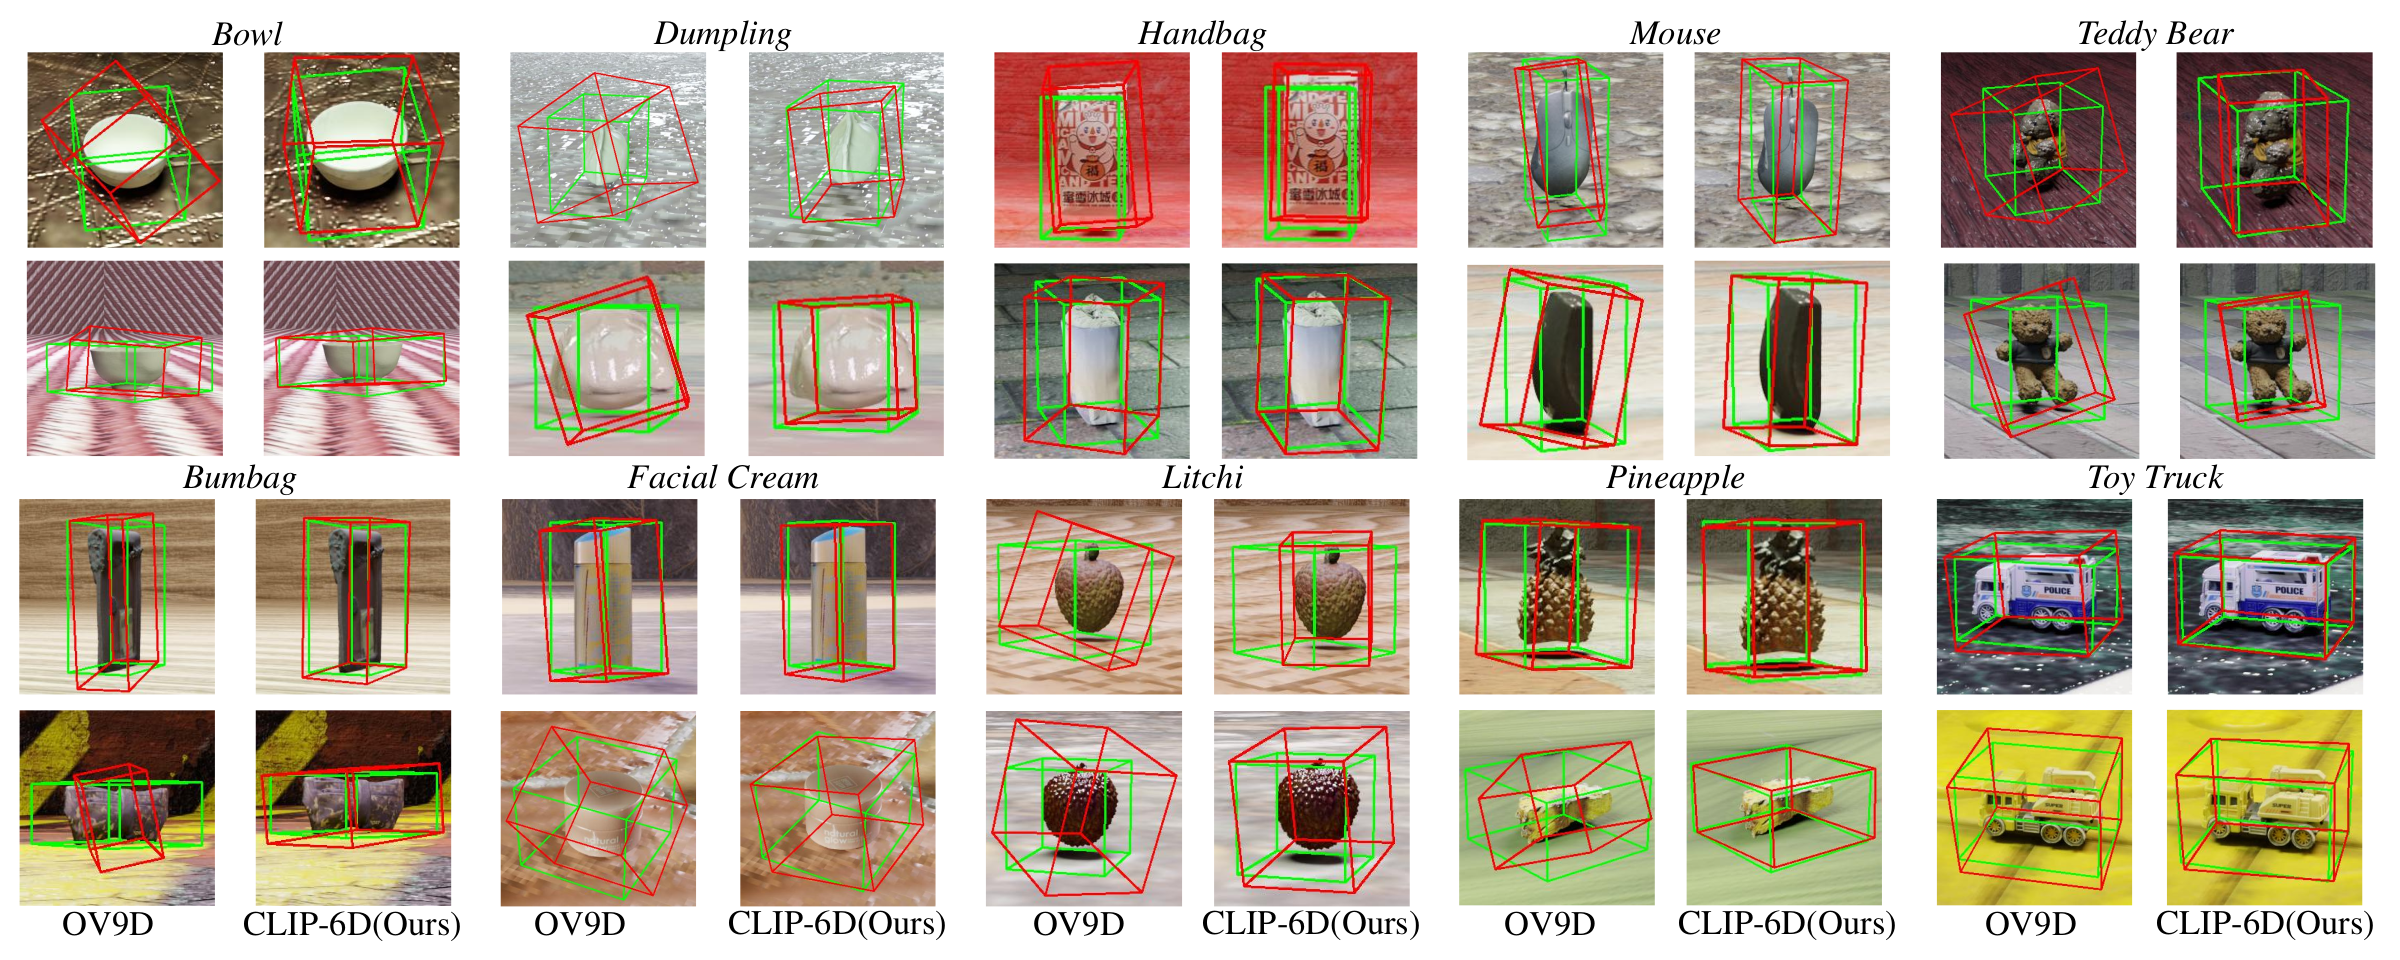
Unseen categories. On OO3D-9D, 230 instances from 10 categories are held out from training. CLIP-6D improves the average results over OV9D under the same evaluation protocol.
All 10 categories and the average, in mAP (%). Higher is better; bold marks the higher score in each pair. On smaller screens, scroll horizontally to view all six criteria.
| Category | 3D IoU ≥ 0.50 | 3D IoU ≥ 0.75 | 5° / 2 cm | 5° / 5 cm | 10° / 5 cm | 10° / 10 cm | ||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| OV9D | CLIP-6D | OV9D | CLIP-6D | OV9D | CLIP-6D | OV9D | CLIP-6D | OV9D | CLIP-6D | OV9D | CLIP-6D | |
| Bowl † | 96.5 | 98.3 | 40.0 | 54.8 | 41.8 | 52.2 | 42.0 | 52.2 | 62.5 | 71.0 | 62.5 | 71.0 |
| Bumbag ‡ | 42.0 | 98.8 | 0.7 | 55.3 | 4.9 | 23.8 | 11.1 | 23.8 | 41.8 | 64.0 | 41.8 | 64.0 |
| Dumpling ‡ | 59.3 | 96.5 | 1.4 | 52.8 | 1.9 | 7.7 | 1.9 | 7.7 | 11.1 | 30.7 | 11.1 | 30.7 |
| Facial cream ‡ | 93.5 | 98.3 | 38.5 | 40.5 | 34.6 | 40.7 | 34.6 | 40.7 | 52.8 | 57.9 | 52.8 | 57.9 |
| Handbag ‡ | 81.8 | 97.6 | 26.2 | 63.2 | 16.1 | 35.6 | 22.1 | 35.6 | 53.6 | 70.2 | 54.9 | 70.2 |
| Litchi † | 85.0 | 99.9 | 22.1 | 52.4 | 7.0 | 18.5 | 7.0 | 18.5 | 18.5 | 39.0 | 18.5 | 39.0 |
| Mouse * | 38.0 | 84.5 | 4.0 | 39.6 | 6.4 | 12.6 | 6.4 | 12.6 | 17.7 | 30.0 | 17.7 | 30.0 |
| Pineapple † | 79.9 | 91.3 | 24.0 | 44.9 | 28.8 | 25.4 | 30.8 | 25.4 | 49.5 | 50.9 | 49.5 | 50.9 |
| Teddy bear * | 75.4 | 97.0 | 7.0 | 30.4 | 0.8 | 3.6 | 1.0 | 3.6 | 5.0 | 14.6 | 5.0 | 14.6 |
| Toy truck * | 66.9 | 96.1 | 9.9 | 66.0 | 3.2 | 23.7 | 3.2 | 23.7 | 12.4 | 50.4 | 12.4 | 50.4 |
| Average | 72.5 | 95.2 | 17.8 | 52.9 | 14.0 | 24.8 | 15.8 | 24.8 | 33.1 | 49.8 | 33.4 | 49.8 |
† Continuous symmetry; ‡ discrete symmetry; * no symmetry.
Scores are mean average precision (mAP). For 5° / 2 cm, both rotation and translation errors must fall within those limits. IoU measures 3D box overlap. OO3D-9D is synthetic with little translation variation, so rotation is the main challenge. Values are reported in the paper; OV9D uses its released weights and test code.
Efficiency. The paper reports 15.77 FPS on one RTX 4090, compared with 10.34 FPS for OV9D, with 74.46M trainable parameters.
Synthetic-to-real transfer. Training on CAMERA25 and testing on REAL275 gives 56.4% mAP at 5° / 2 cm and 87.2% at 10° / 5 cm. This tests domain transfer within six shared categories, rather than unseen-category generalization.
Real-world examples
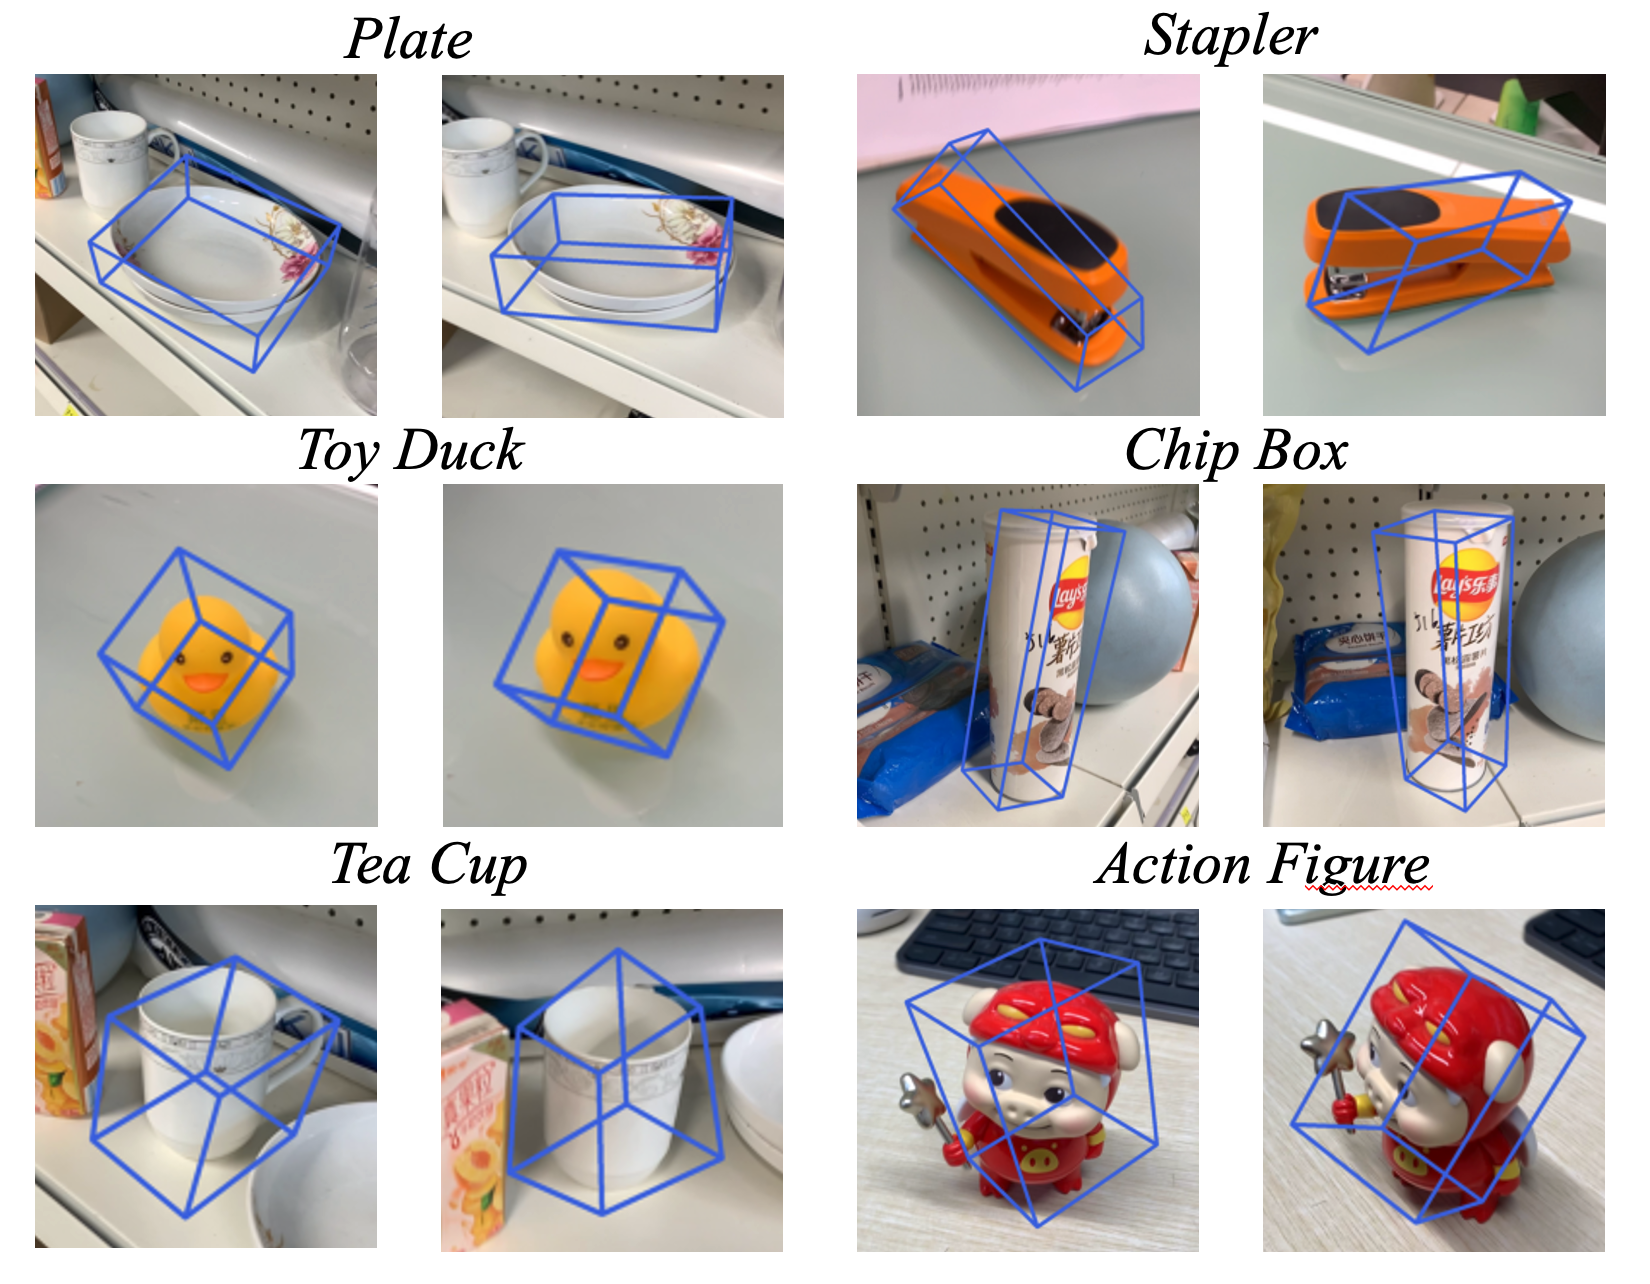
The method still depends on depth and can struggle with objects whose shapes vary widely, such as sculptures and artworks.
My contribution
As first author, I led the research, method design, implementation, training, and evaluation.
Figures and results are from the CLIP-6D paper, ACM Multimedia 2025.