RCSPose
Revisiting Category Semantics in Category-Level 6D Object Pose Estimation
IEEE/RSJ IROS 2026 · Accepted
RCSPose uses RGB-D observations and category labels to predict 3D position, 3D orientation, and object size for new instances of known categories, without explicit shape priors.
Motivation
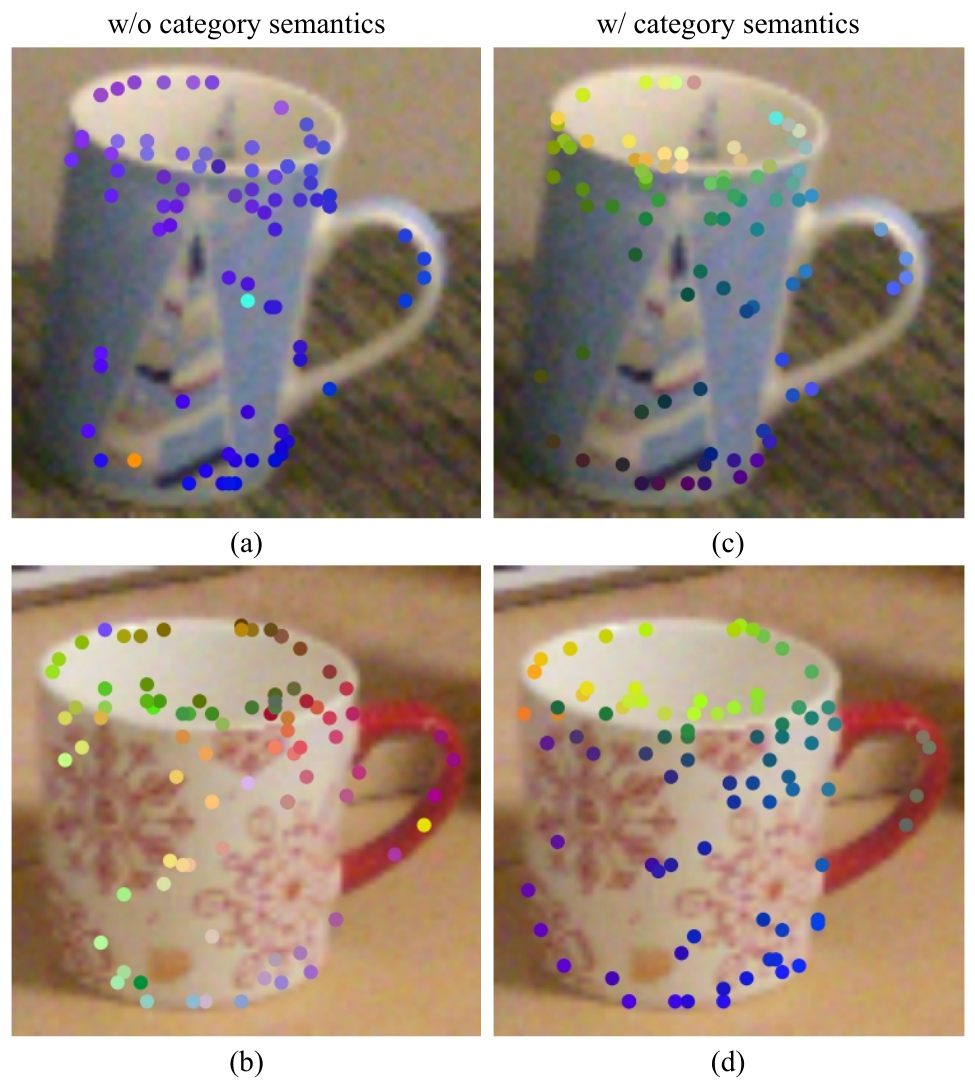
Two mugs can have very different shapes, yet share a handle, rim, and body. Category-level pose estimation needs features that capture these shared structures while preserving what makes each instance different.
RCSPose revisits category labels as a guide for learning these features. It combines cleaner depth geometry, semantics from multiple visual-network layers, and category-guided attention to handle shape variation within a category.
How it works
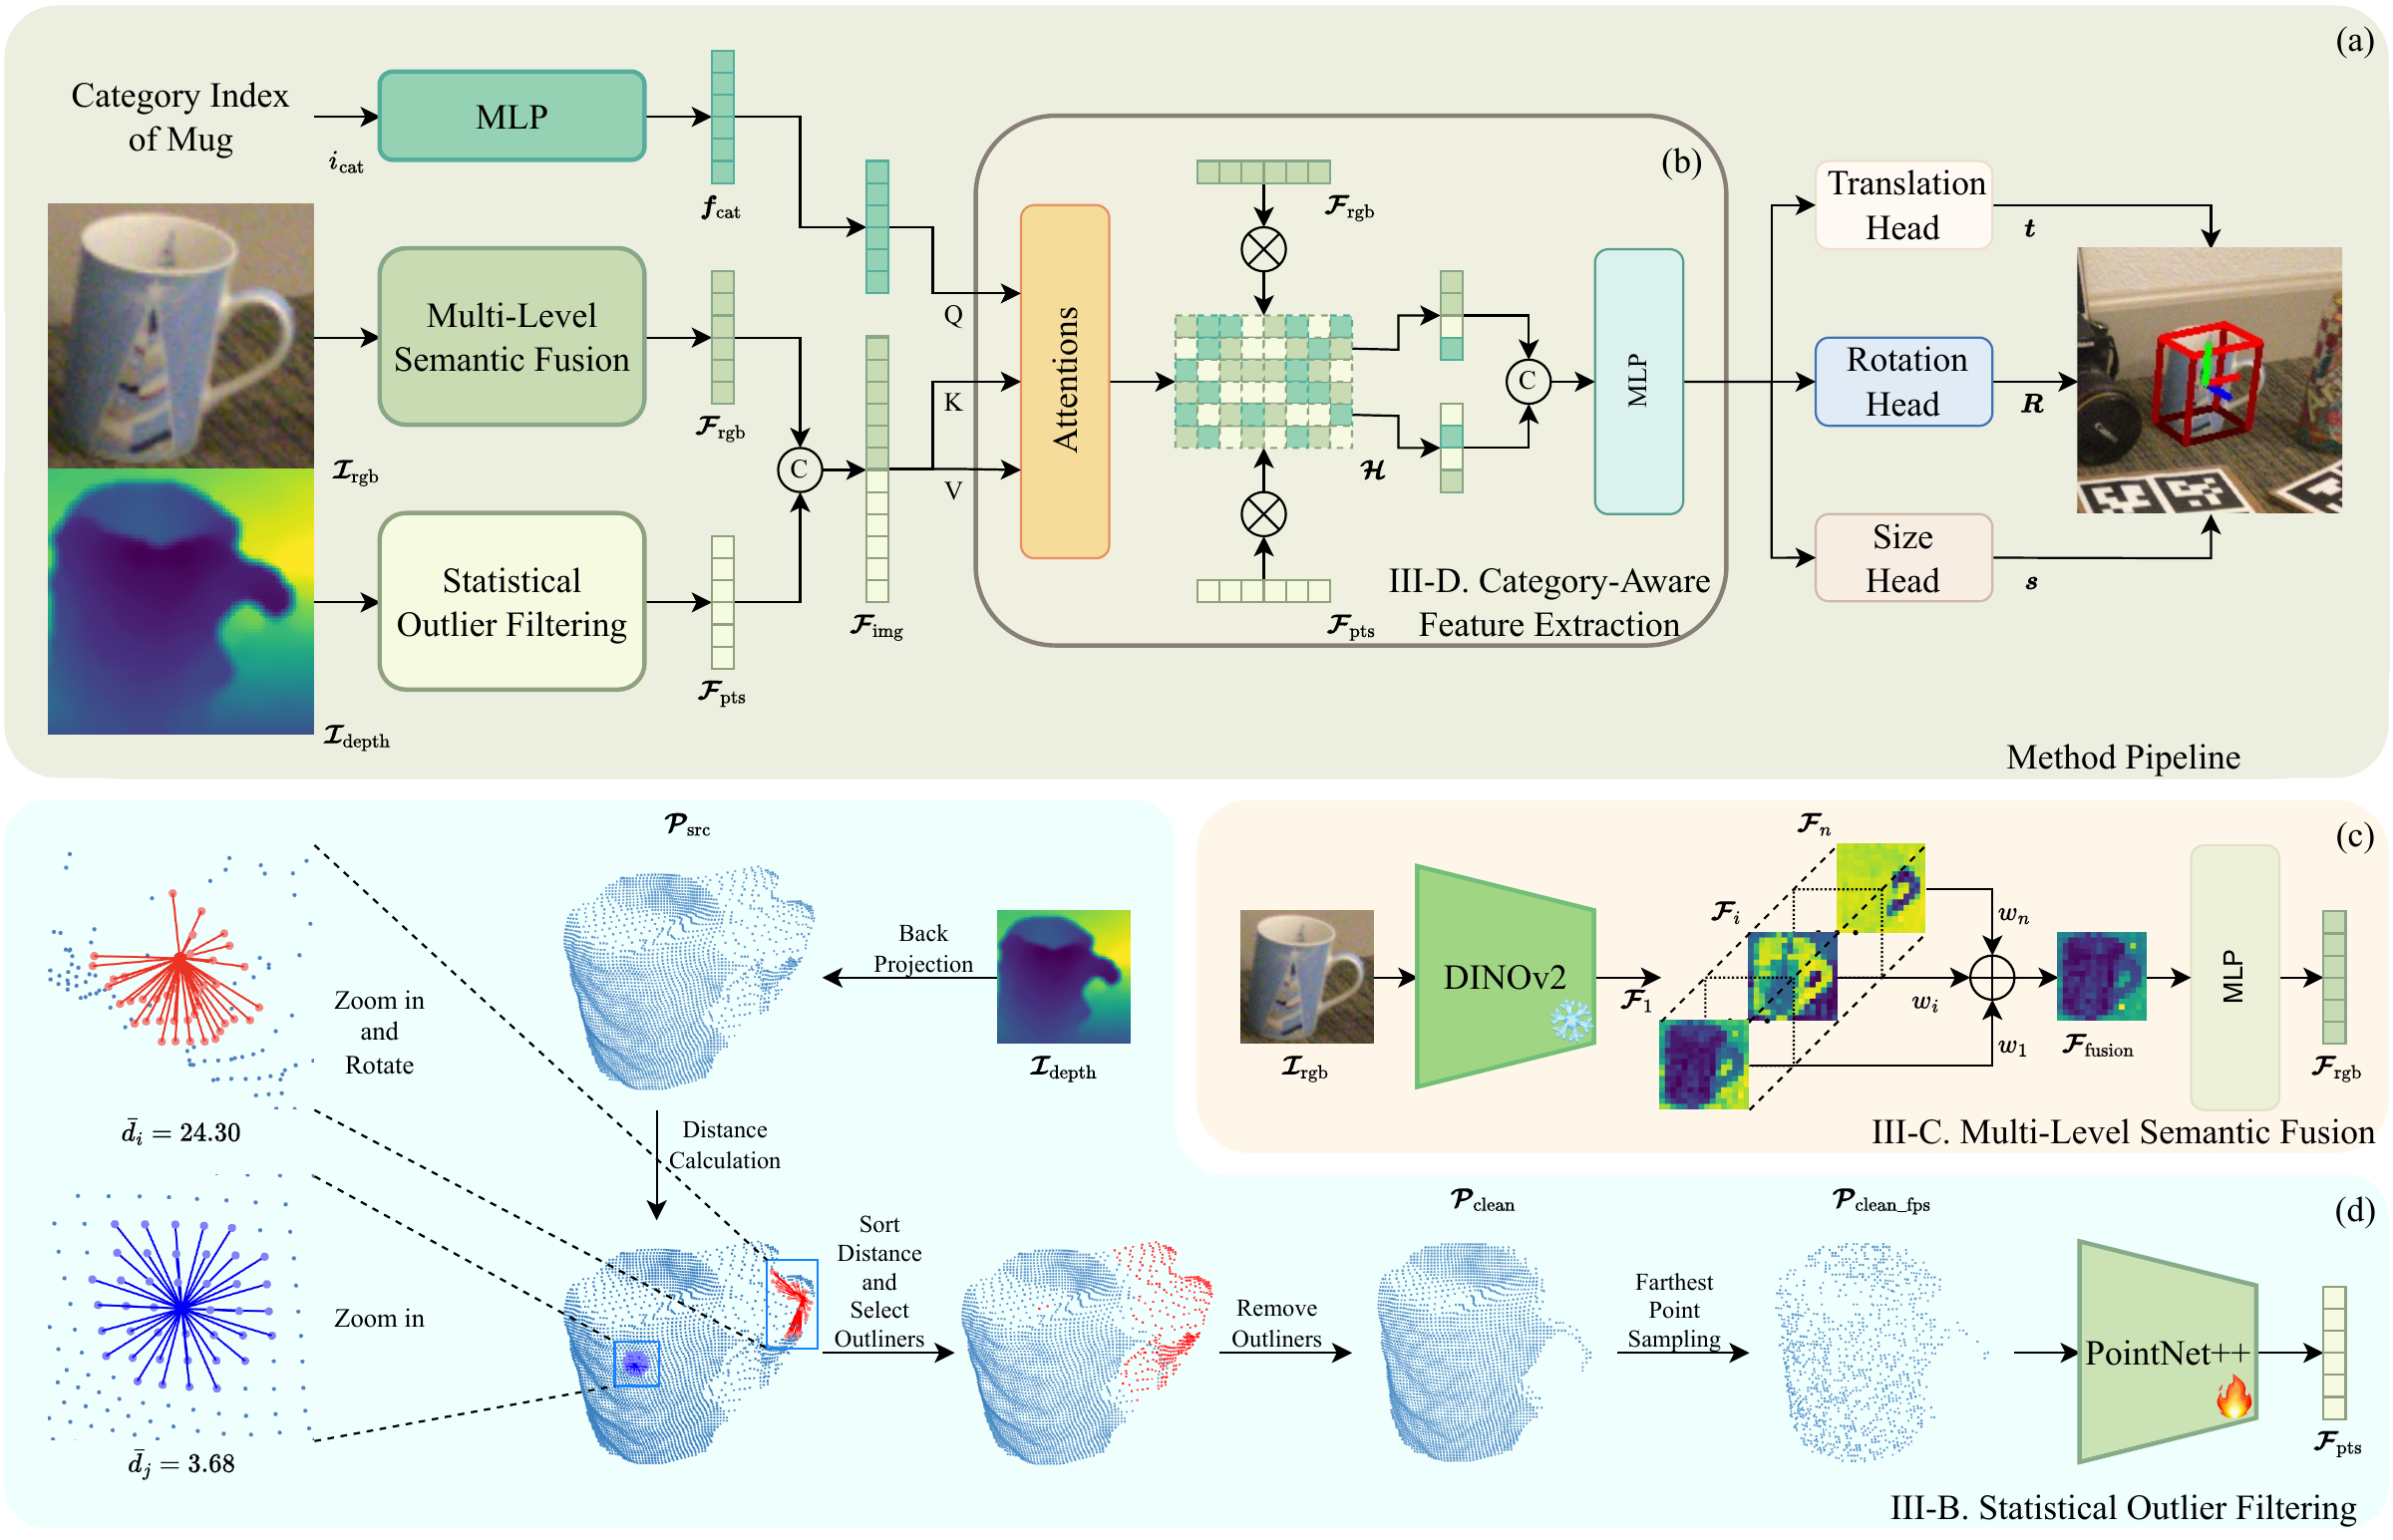
An instance segmenter supplies object masks and category labels. Camera intrinsics turn the cropped depth image into a point cloud; the model combines this geometry with the RGB crop and category label. It learns from labeled data and needs no object CAD model or category shape template at inference.
SOF · Clean geometry
Use local neighbor-distance statistics to remove isolated depth points, then sample a consistent point set and extract geometric features with PointNet++.
MLSF · Fuse visual layers
Learned weights combine features from the last four DINOv2 blocks, bringing together complementary appearance and semantic cues.
CAFE · Use category cues
Category embeddings guide attention over RGB and point-cloud features. The resulting heatmap focuses feature aggregation on category-relevant structures.
Closer look: what each module contributes
On REAL275 at 5° / 2 cm, the simplified baseline scores 56.3%. Adding SOF alone gives 58.4%, MLSF alone 57.5%, and CAFE alone 57.9%; the full model reaches 60.6%. Geometry cleanup and both semantic modules contribute to the final result.
Results
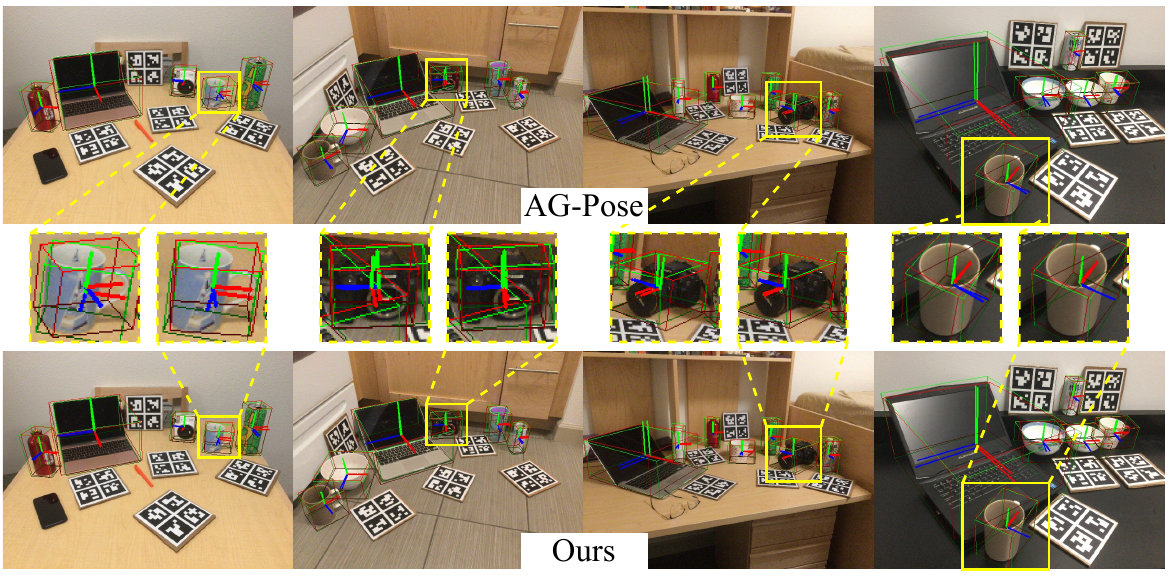
On REAL275, RCSPose reaches 60.6% mAP at 5° / 2 cm, compared with 54.7% for AG-Pose. On HouseCat6D, it reaches 83.6% mAP at 3D IoU ≥ 0.50, compared with 76.9% for AG-Pose.
RCSPose results across three datasets · mAP (%) · higher is better. On narrow screens, scroll horizontally to view every dataset. A dash means the criterion is not reported in the source table.
| Criterion | REAL275 | CAMERA25 | HouseCat6D |
|---|---|---|---|
| 3D IoU ≥ 0.25 | — | — | 92.3 |
| 3D IoU ≥ 0.50 | 83.9 | 94.2 | 83.6 |
| 3D IoU ≥ 0.75 | 80.4 | 92.2 | — |
| 5° / 2 cm | 60.6 | 79.8 | 24.6 |
| 5° / 5 cm | 67.4 | 83.4 | 26.7 |
| 10° / 2 cm | 80.4 | 87.3 | 56.0 |
| 10° / 5 cm | 88.4 | 92.1 | 59.9 |
IoU measures 3D bounding-box overlap. A 5° / 2 cm prediction must satisfy both the rotation and translation limits. The REAL275 evaluation uses both synthetic and real training data. Values come from Tables I and II of the paper.
Category-wise results and comparisons
Selected comparisons with AG-Pose from Tables III and IV. Bold marks the higher score in each pair, including ties.
| Category | RCSPose | AG-Pose |
|---|---|---|
| Bottle | 73.4 | 62.0 |
| Bowl | 94.4 | 88.7 |
| Camera | 4.8 | 1.2 |
| Can | 82.3 | 83.4 |
| Laptop | 69.7 | 59.6 |
| Mug | 38.8 | 32.9 |
| Mean | 60.6 | 54.7 |
| Category | RCSPose | AG-Pose |
|---|---|---|
| Bottle | 90.7 | 86.0 |
| Box | 21.6 | 13.9 |
| Can | 93.6 | 96.7 |
| Cup | 99.9 | 99.9 |
| Remote | 69.1 | 37.2 |
| Teapot | 99.5 | 98.5 |
| Cutlery | 97.7 | 93.3 |
| Glass | 99.9 | 99.3 |
| Tube | 64.0 | 45.0 |
| Shoe | 100.0 | 99.5 |
| Mean | 83.6 | 76.9 |
Performance varies by criterion. For example, on HouseCat6D at 5° / 2 cm, GCE-Pose with shape priors reports 24.8%, compared with 24.6% for RCSPose.
Real-world examples
The paper tests new instances of six known categories in new environments. RGB images and camera intrinsics are captured with OnePose Cap; Depth Anything V2 supplies predicted depth for the model.
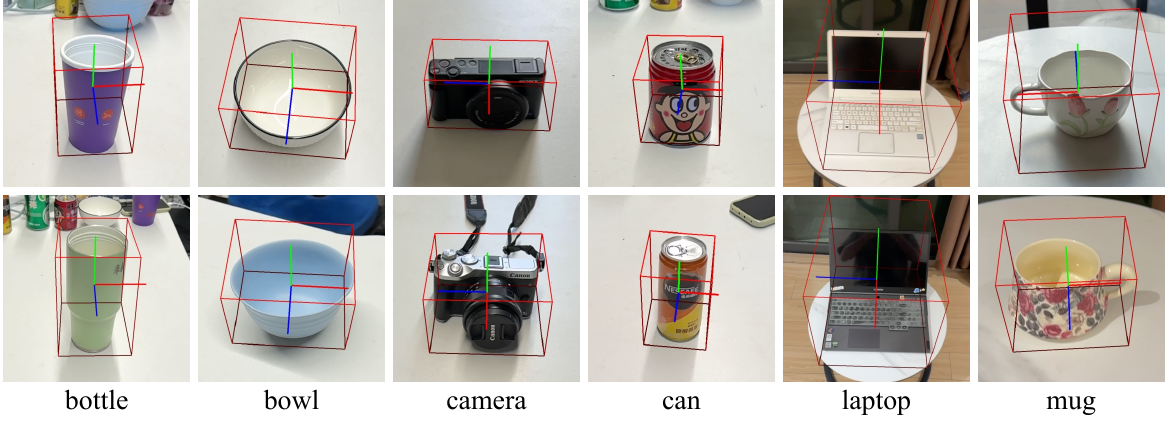
The model still requires depth, so the quality and availability of depth remain practical limits.
Figures and results are from the RCSPose paper, IEEE/RSJ IROS 2026.