ROM-6D
Relational Object Memories for CAD-Free Multi-Object 6D Pose Estimation
Ongoing research · Planned submission to CVPR 2027
ROM-6D estimates multiple objects’ 3D positions and 3D orientations from a single RGB image and posed reference images. Each object can use its own visual evidence or draw on geometric support from other objects, without CAD models or query depth.
Motivation
Some objects in an image are easy to recognize, while others are partly hidden or have few distinctive features. Estimating every object independently leaves difficult targets unable to benefit from their clearly visible neighbors.
Combining all objects into one shared estimate also has a drawback: noisy matches or changed object arrangements can hurt otherwise reliable predictions. ROM-6D instead asks, for each target: which other objects can help, and when should it rely on its own estimate?
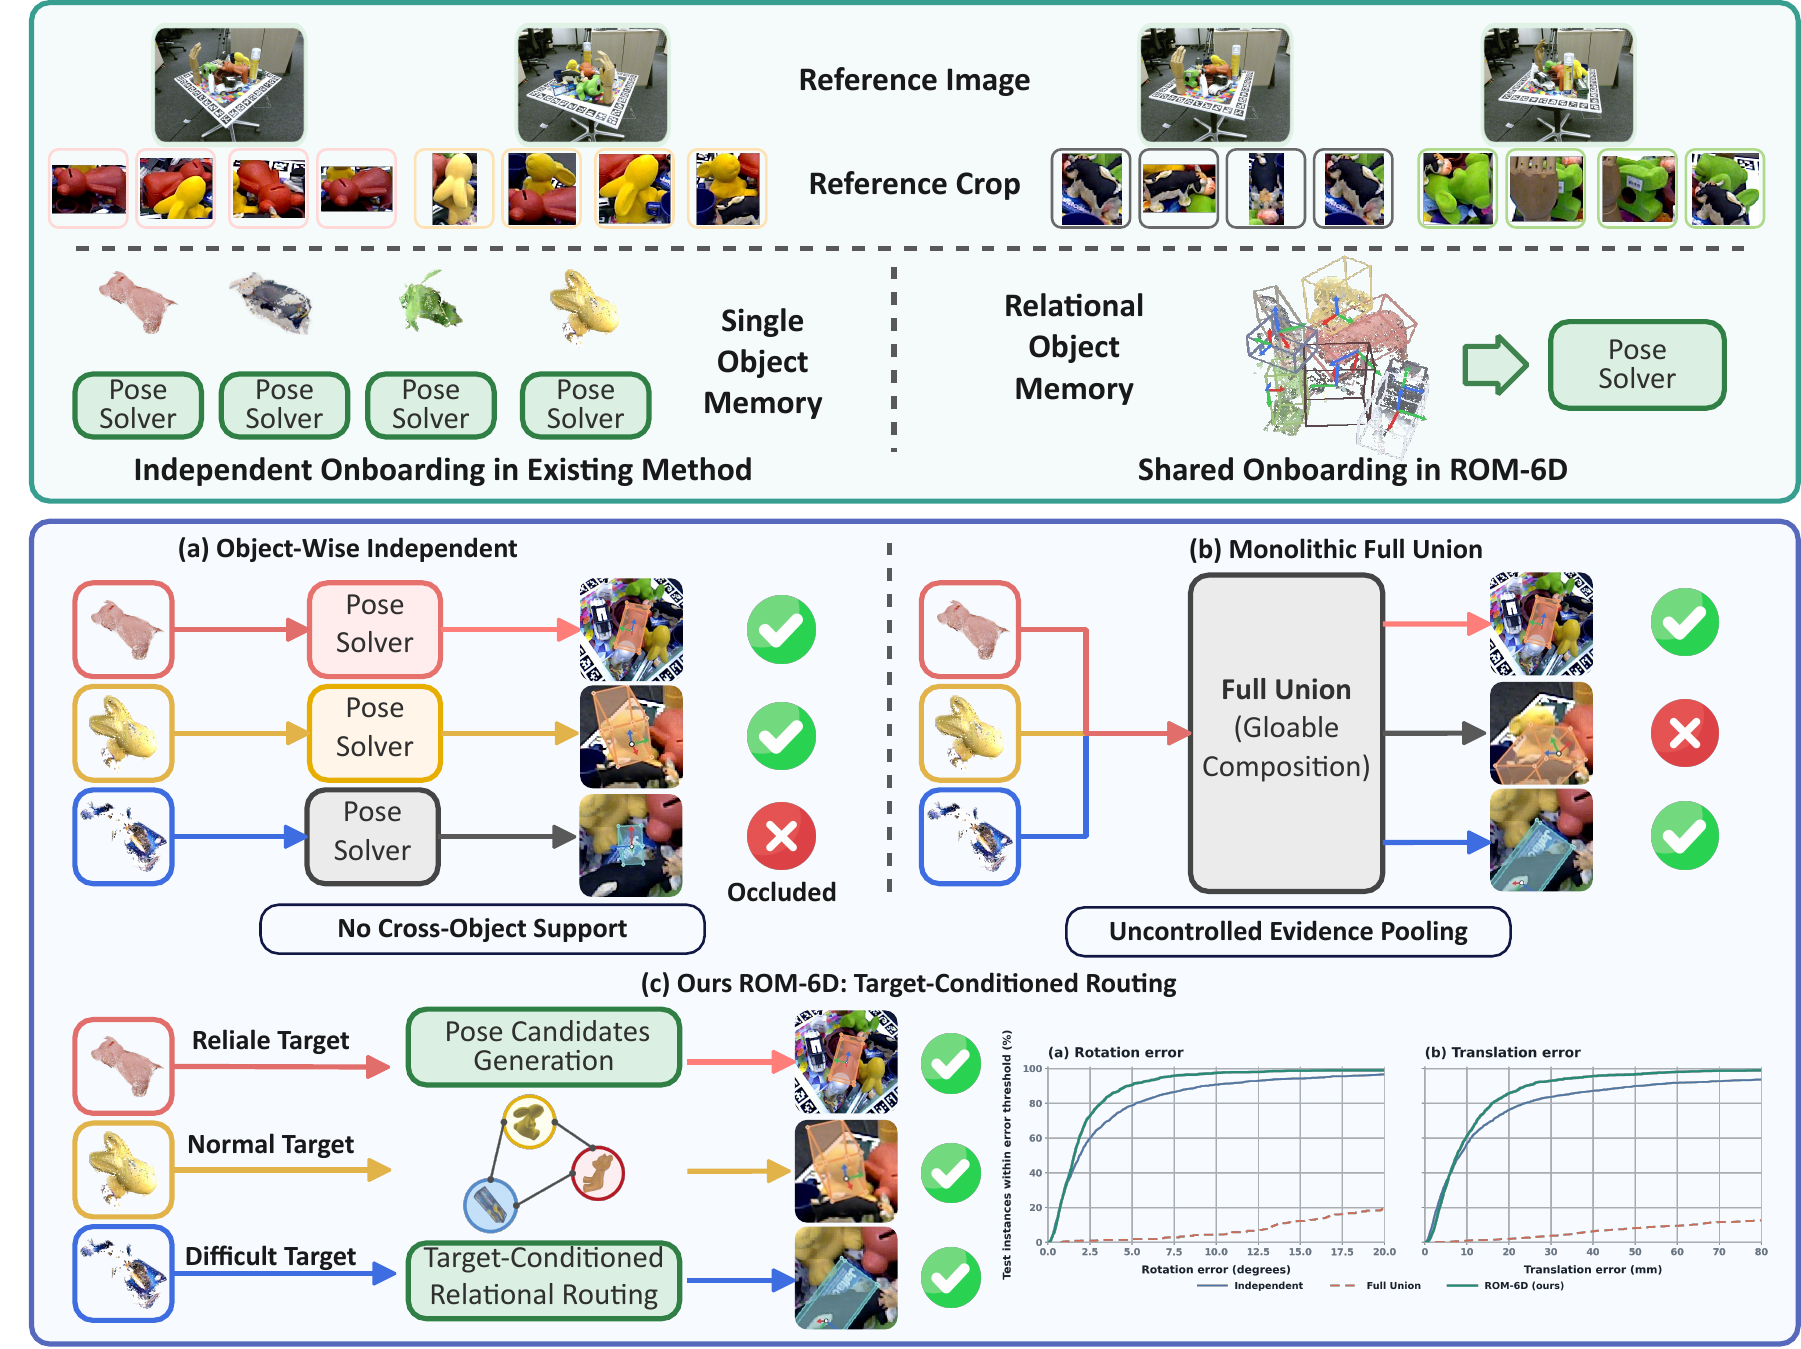
How it works
Setup uses shared RGB reference images with camera calibration, object regions, and known object poses. At inference, the method takes one RGB image, camera intrinsics, and identified object regions. The reported main experiments use ground-truth bounding boxes for both references and queries.
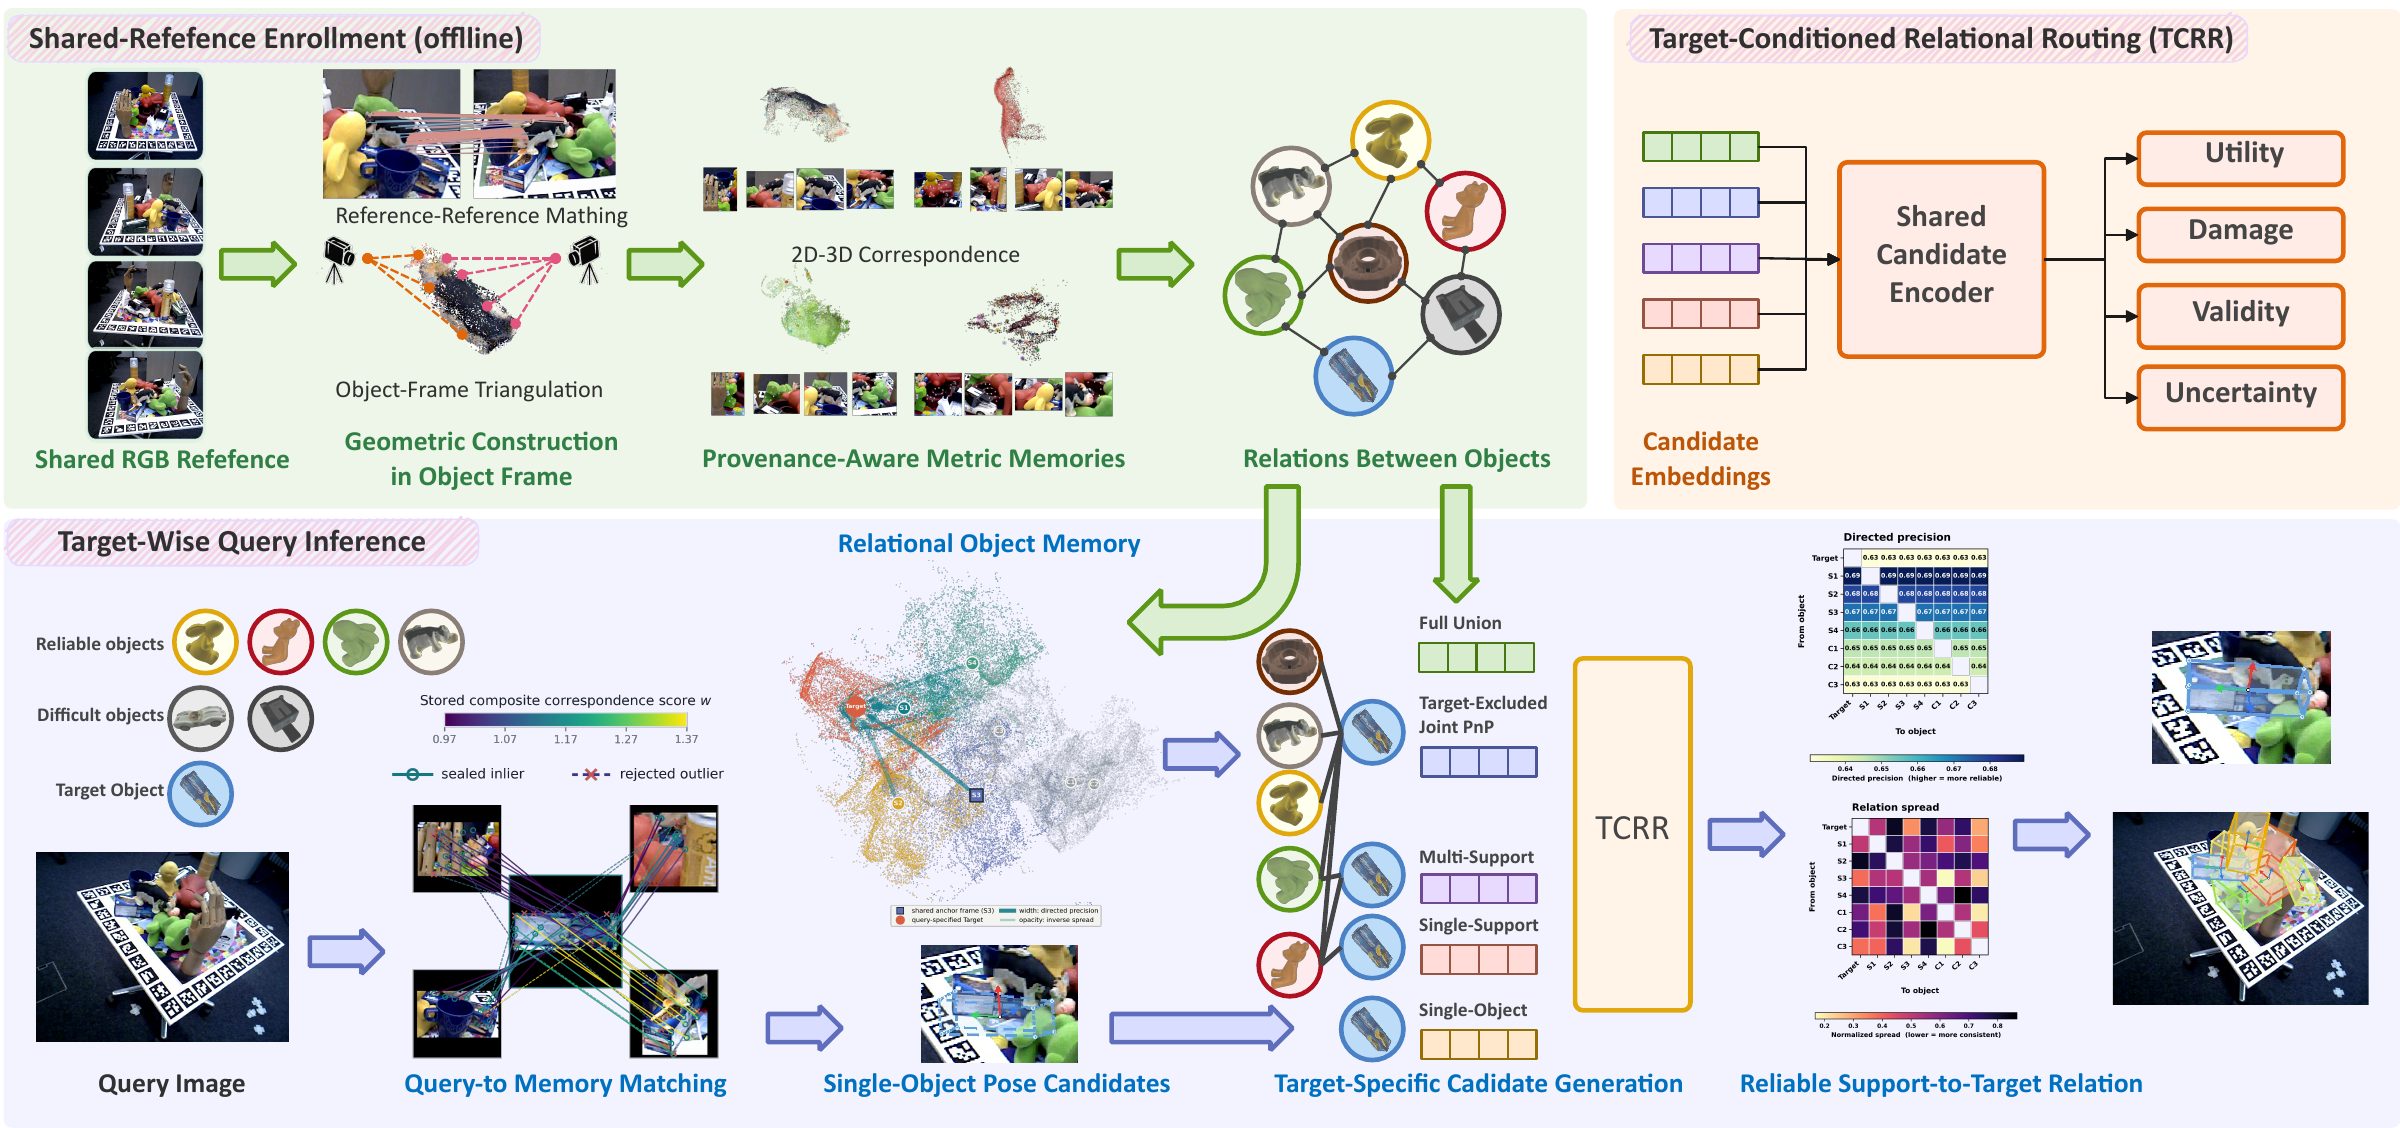
Build object memories
Match reference views with a frozen RoMaV2 matcher and triangulate 3D landmarks in each object’s coordinate frame. Store relative transforms between co-observed objects.
Generate pose candidates
First solve each object independently. Then generate alternatives using one or several other objects as supports, with a full-union estimate as an optional candidate.
Choose per target
Target-Conditioned Relational Routing (TCRR) weighs expected pose quality, relation validity, damage risk, and uncertainty. Different targets can select different sources of evidence.
Memory construction and geometric candidate generation need no task-specific training. TCRR is learned from candidate-selection episodes, primarily built from MegaPose train-PBR images; the whole pipeline is not training-free.
Results
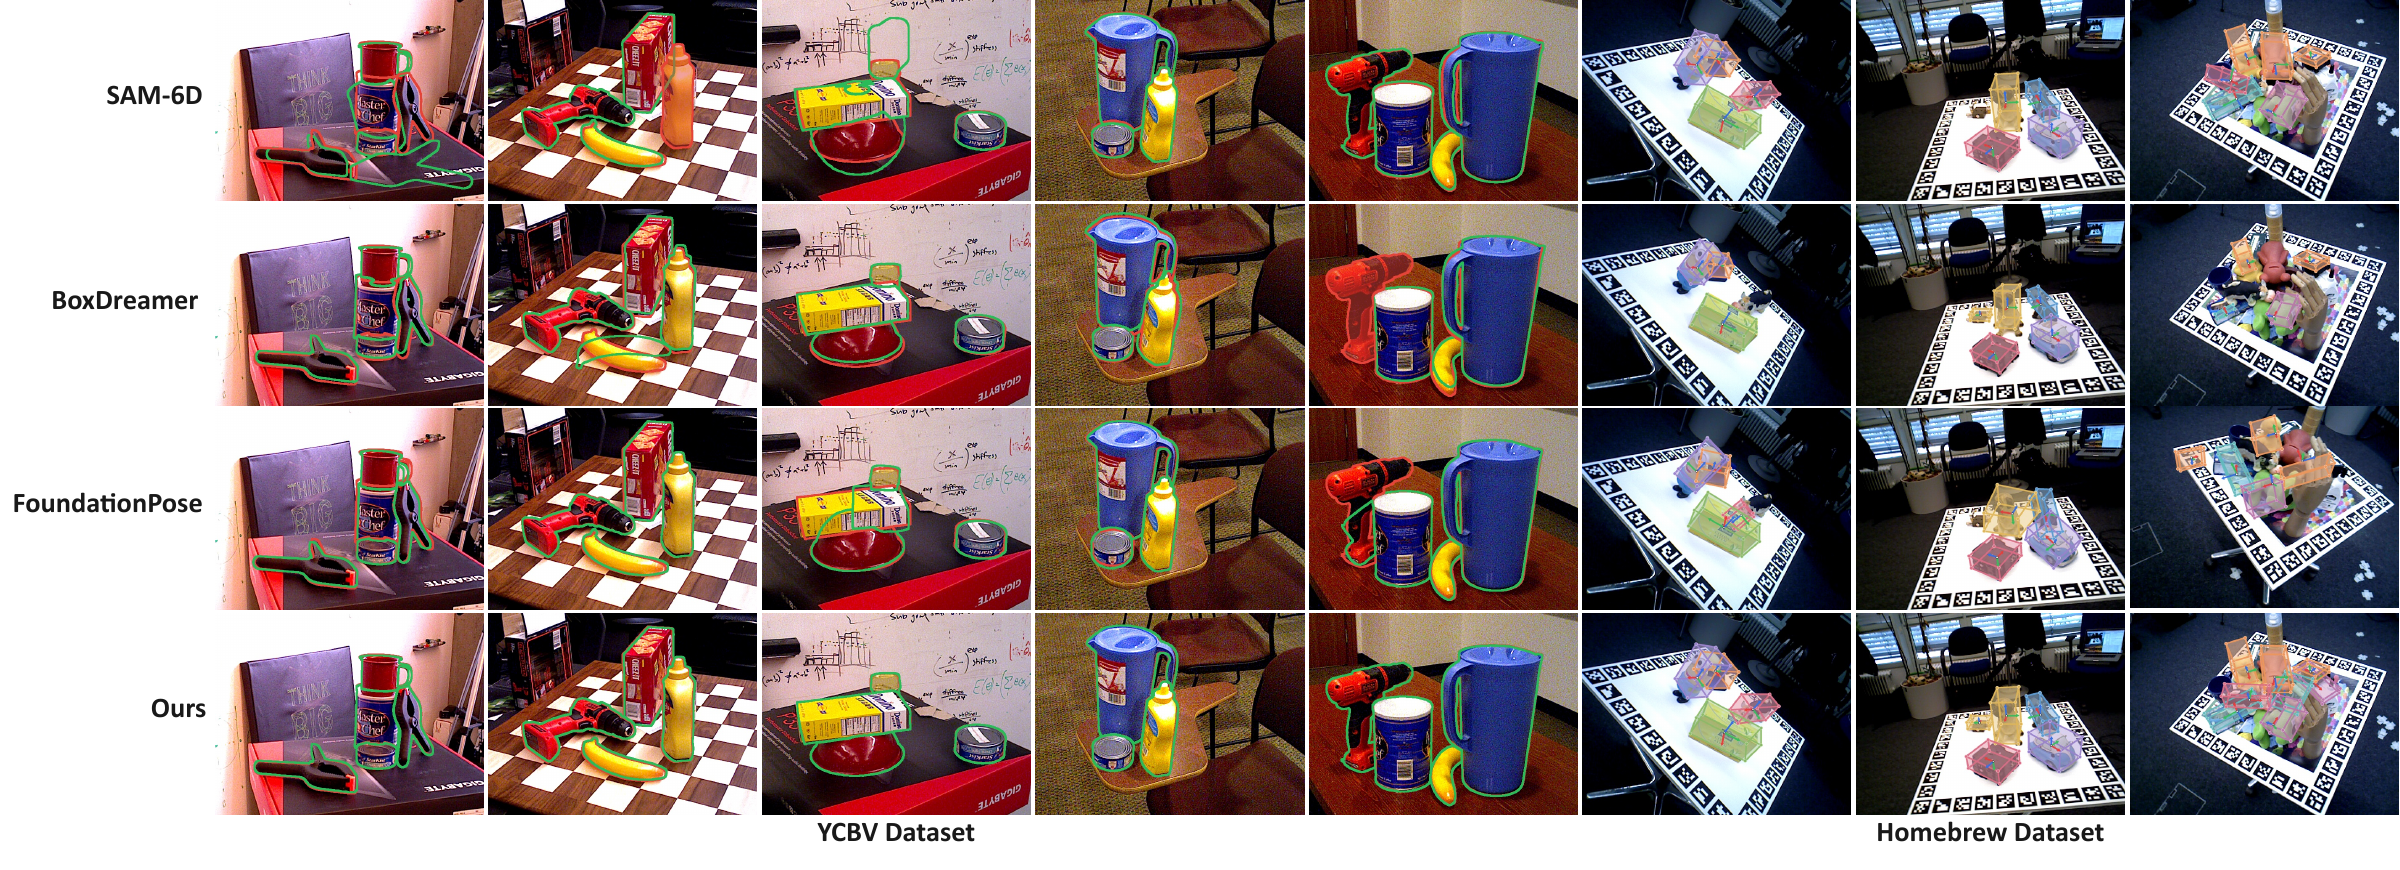
With four shared reference images, ROM-6D reports 96.4% ADD(-S) accuracy and 95.2% Average Recall on YCB-V. The controlled comparison covers five BOP datasets; ROM-6D has the highest AR on four of them, while FoundationPose-MF leads on IC-BIN.
Current draft results · Four shared references and ground-truth object boxes · Average Recall (%, higher is better). Bold marks the best score in each column. On narrow screens, scroll horizontally to view all datasets.
| Method | YCB-V | T-LESS | LM-O | IC-BIN | HB |
|---|---|---|---|---|---|
| Gen6D | 33.6 | 6.3 | 42.1 | 5.5 | 11.7 |
| OnePose | 8.5 | 0.0 | 0.0 | 0.0 | 0.0 |
| OnePose++ | 16.5 | 0.0 | 20.5 | 0.0 | 0.0 |
| GS-Pose | 82.0 | 25.5 | 57.2 | 7.0 | 24.0 |
| BoxDreamer | 68.2 | 44.3 | 57.5 | 23.4 | 19.2 |
| FoundationPose-MF | 82.9 | 3.9 | 11.3 | 40.2 | 13.1 |
| ROM-6D | 95.2 | 59.6 | 82.9 | 21.4 | 68.1 |
Values are from the draft’s controlled comparison, rather than its separate richer-input comparisons. AR averages recall over the BOP visible-surface, 3D surface, and 2D projection error criteria. ADD(-S) above uses the 0.1-object-diameter threshold. These are preliminary manuscript results.
Efficiency: pruning pose candidates
On the same fixed 60-frame YCB-V subset, Fast ROM-6D reduces mean latency from 27.97 to 10.84 seconds per multi-object query (2.58×), with ADD(-S) changing from 97.55% to 97.38%. It prunes relational candidates before PnP while keeping the router frozen. Timings use one RTX 4090 and exclude detection, disk I/O, evaluation, and offline memory construction; the implementation is not real-time.
Different objects, different decisions
When objects move, relations stored during setup may become outdated. In the LM-O relation-change diagnostic, TCRR reaches 23.22% ADD(-S), compared with 14.94% for independent PnP and 10.67% for unconditional full union. This diagnostic tests changing reference layouts and is separate from the standard BOP benchmark.
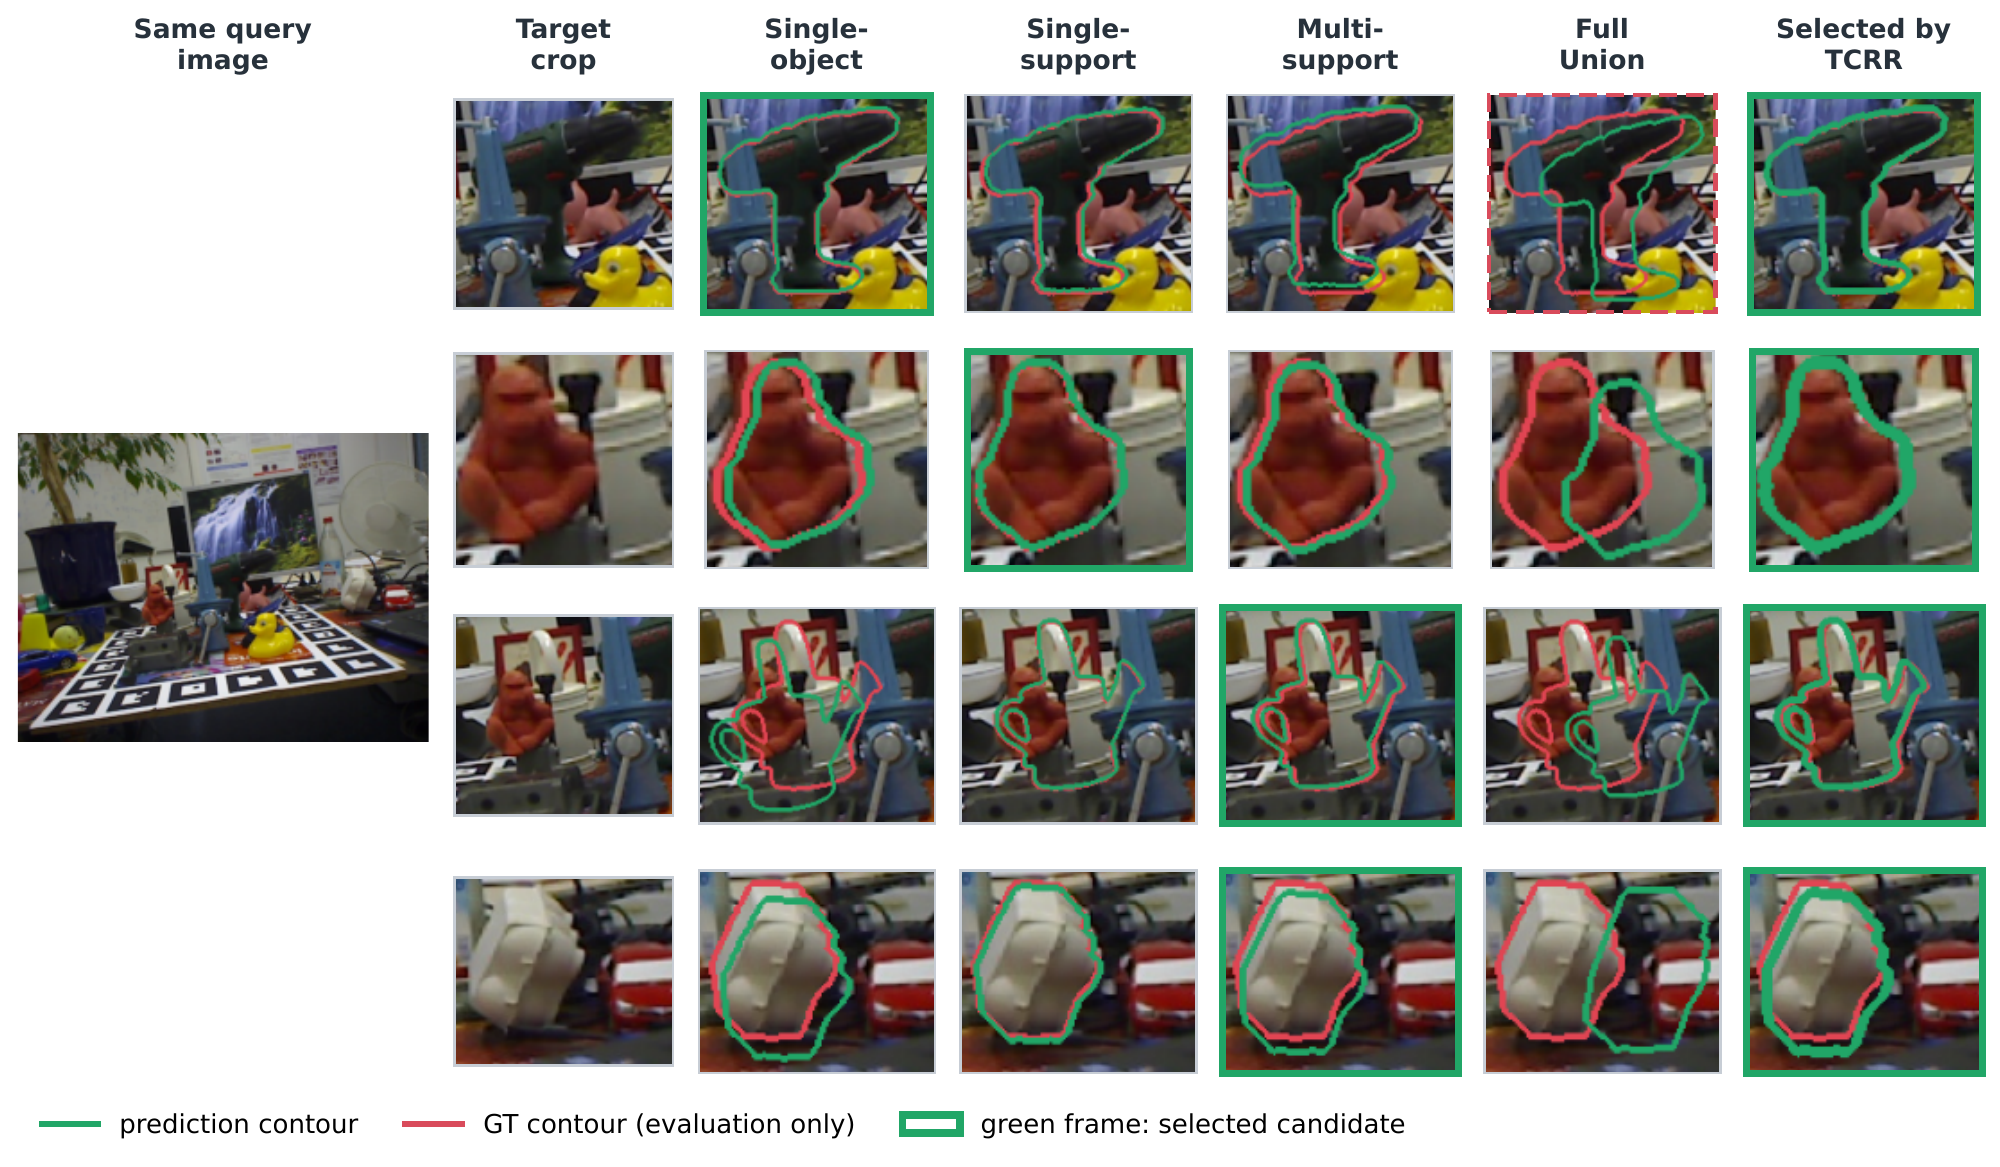
Current scope. The method assumes identified object regions and calibrated, posed references. Routing cannot reject every outdated relation, and same-scene results do not establish generalization across backgrounds.
Figures and results are from the current ROM-6D draft. This work is in progress, with submission to CVPR 2027 planned.